The Pendulums of Data
Follow into
Save into
Follow into
A few years ago, decentralization was all the rage in data. Data mesh, domain ownership, self-service, decentralized pipelines, schema-on-read, and letting teams own their own data products were supposed to free us from the bottlenecks of centralized data teams and platforms. Before that, of course, we spent decades centralizing data into warehouses because scattered data was a mess. Now we’re talking again about common platforms, centralized governance, shared semantic layers, data contracts, and how to govern AI agents. What’s old is new again.
People love to think in straight lines, as if the future is knowable. As I recently wrote, nobody knows. Linear thinking rarely serves anyone, as many other effects drive the world. Extrapolation is convenient, but rarely correct. This is one recurring pattern I’ve noticed over my career: the data industry doesn’t move in a straight line. It moves through a collection of pendulums. Centralized versus decentralized. Batch versus real-time. General-purpose versus specialized. Rigorous versus informal. Normalized versus denormalized. Governance versus self-service. Even OLTP versus OLAP is a tension we’ve been messing around with forever. Now, it’s classic ML (written off as dead) vs. AI, thanks to Jev.
As tempting as it is to assume one side wins, they often don’t. It’s more like a couple who argue a lot. Nobody really wins per se. Instead, they oscillate around a set of tensions, volleying arguments back and forth, with the pendulum swinging in one’s favor, then another. But if you’ve been there, nobody ever comes out ahead. A couple’s therapist might suggest looking at why these arguments happen in the first place. But I digress. Back to data.
Take centralization and decentralization. We centralize because complexity gets out of control. Infrastructure, schemas, governance, platforms, teams, and decisions gradually move toward the center because coordinating all of this stuff independently becomes a nightmare. Eventually, though, the central system slows and becomes bureaucratic. It gets detached from the business, the specs, and the domain knowledge of the people doing the work. The process can become a ceremony unto itself.
So the argument flips. Centralization is the problem! Decentralize everything! We get data mesh, microservices, domain-driven design, self-service, embedded analytics, decentralized pipelines, and teams owning their own data products. This works for a while and solves some legitimate problems. People can move faster. But eventually you get duplicate work, inconsistent artifacts, silos, and enormous coordination overhead.
And then the pendulum starts swinging back. Suddenly platform engineering sounds pretty good. So do common metadata, centralized governance, shared semantic layers, and data contracts.
The feedback loop looks something like this: centralize until you create bottlenecks, decentralize until you create fragmentation, standardize to deal with the fragmentation, and then recentralize the things that are difficult to coordinate independently. Rinse and repeat.
The important thing is that we don’t return to the same place. Maybe we decentralize compute while centralizing metadata, identity, policy, and semantics. The technology and boundaries change even if the underlying tension doesn’t. One lesson that keeps popping up is that execution can decentralize much more easily than coordination. You don’t realize how much coordination matters until you don’t have it.
Speed has its own pendulum. For decades, the trajectory looked almost completely one-directional: monthly reports became nightly batches, then hourly pipelines, then streaming and real-time systems, and now we’re talking about AI agents responding and taking action almost instantly. Nobody is arguing that we should go back to waiting a month for a report just for the hell of it. Faster technology is genuinely useful.
But as I wrote in last week’s post, This Year’s Better Mousetrap, the hard problems have a funny habit of sticking around. We can throw faster and more sophisticated technology at the problem, but organizational friction, unclear ownership, fuzzy meanings, coordination, and disagreement don’t magically disappear. Sometimes technology just gets us to the same old problem much faster. If we’re enlightened, we treat this fast feedback loop as a way to get ourselves out of a hole. More likely, we use the fast feedback loop to dig an even deeper hole.
Schema-on-read is a good example. Throwing data into a lake without modeling everything upfront was a real advancement because it removed friction and let people move faster. In some cases it worked, and teams who knew what they were doing benefited from schema-on-read. Most weren’t so lucky. Schema-on-read didn’t absolve anyone of the technical debt and data debt created along the way. You simply moved some of the work somewhere else. There’s no free lunch.
I think every generation also tends to confuse “faster is possible” with “faster is necessary.” Streaming becomes fashionable, then people rediscover batch. Maybe not everything needs to be a stream. But not everything needs to be batch either. It depends on what you’re trying to accomplish. There is no universal answer, just as there’s no universal data modeling pattern or universal architecture.
AI will probably push the pendulum toward faster architectures again. If agents continuously interpret data, make decisions, and take action, stale data matters far more than it did when someone looked at a dashboard once a week. But autonomous action also raises the consequences of getting things wrong. The faster we let machines act, the more attention we’ll have to pay to security, governance, correctness, semantics, and operational risk. The push for speed creates the counterforce that eventually slows parts of the system back down.
This gets to the larger point. Pendulums are feedback systems. Centralization creates bottlenecks. Decentralization creates coordination problems. Speed creates fragility. Governance creates bureaucracy. Abstraction creates a loss of control. Specialization creates integration complexity. Every architecture eventually becomes its own counterforce. An idea’s success creates the conditions for backlash.
That’s why industry cycles are surprisingly predictable. A winning idea solves a real problem, everyone gets excited about it, and then we overextend it into places where it probably never belonged. Eventually the externalities become obvious, and the opposite idea starts looking attractive again. Familiarity breeds contempt, especially when you’ve spent the last five years dealing with the downsides of whatever paradigm was supposed to save you.
But the pendulum never swings back to the same place. Each cycle leaves behind new infrastructure, practices, expectations, and constraints. In that sense, maybe the better mental model is a pendulum attached to a ratchet. We oscillate between recurring tensions while the underlying capability frontier continues moving forward.
The dangerous phrase in technology is some variation of “this time is different.” Today’s hot architecture is tomorrow’s legacy system, and the clock starts ticking the moment you put it into production. Today’s reaction against complexity creates tomorrow’s complexity.
So when the next supposedly revolutionary architecture, methodology, or AI-powered whatever shows up, I’m less interested in asking whether it’s the future. I’d rather ask what tension it’s temporarily resolving, and what the reaction and backlash will be.
And then I’d ask the more interesting question: what happens if this idea succeeds too well? That’s probably where the next pendulum swing begins, and where I’d focus my attention.
In this Freestyle Friday episode, I chat about the various craziness and trends of data and AI right now.
Freestyle Fridays and my other podcasts are available on Spotify, Apple Podcasts, and wherever you get your podcasts. Please support the show with a review. It means a lot.
Mixed Model Arts
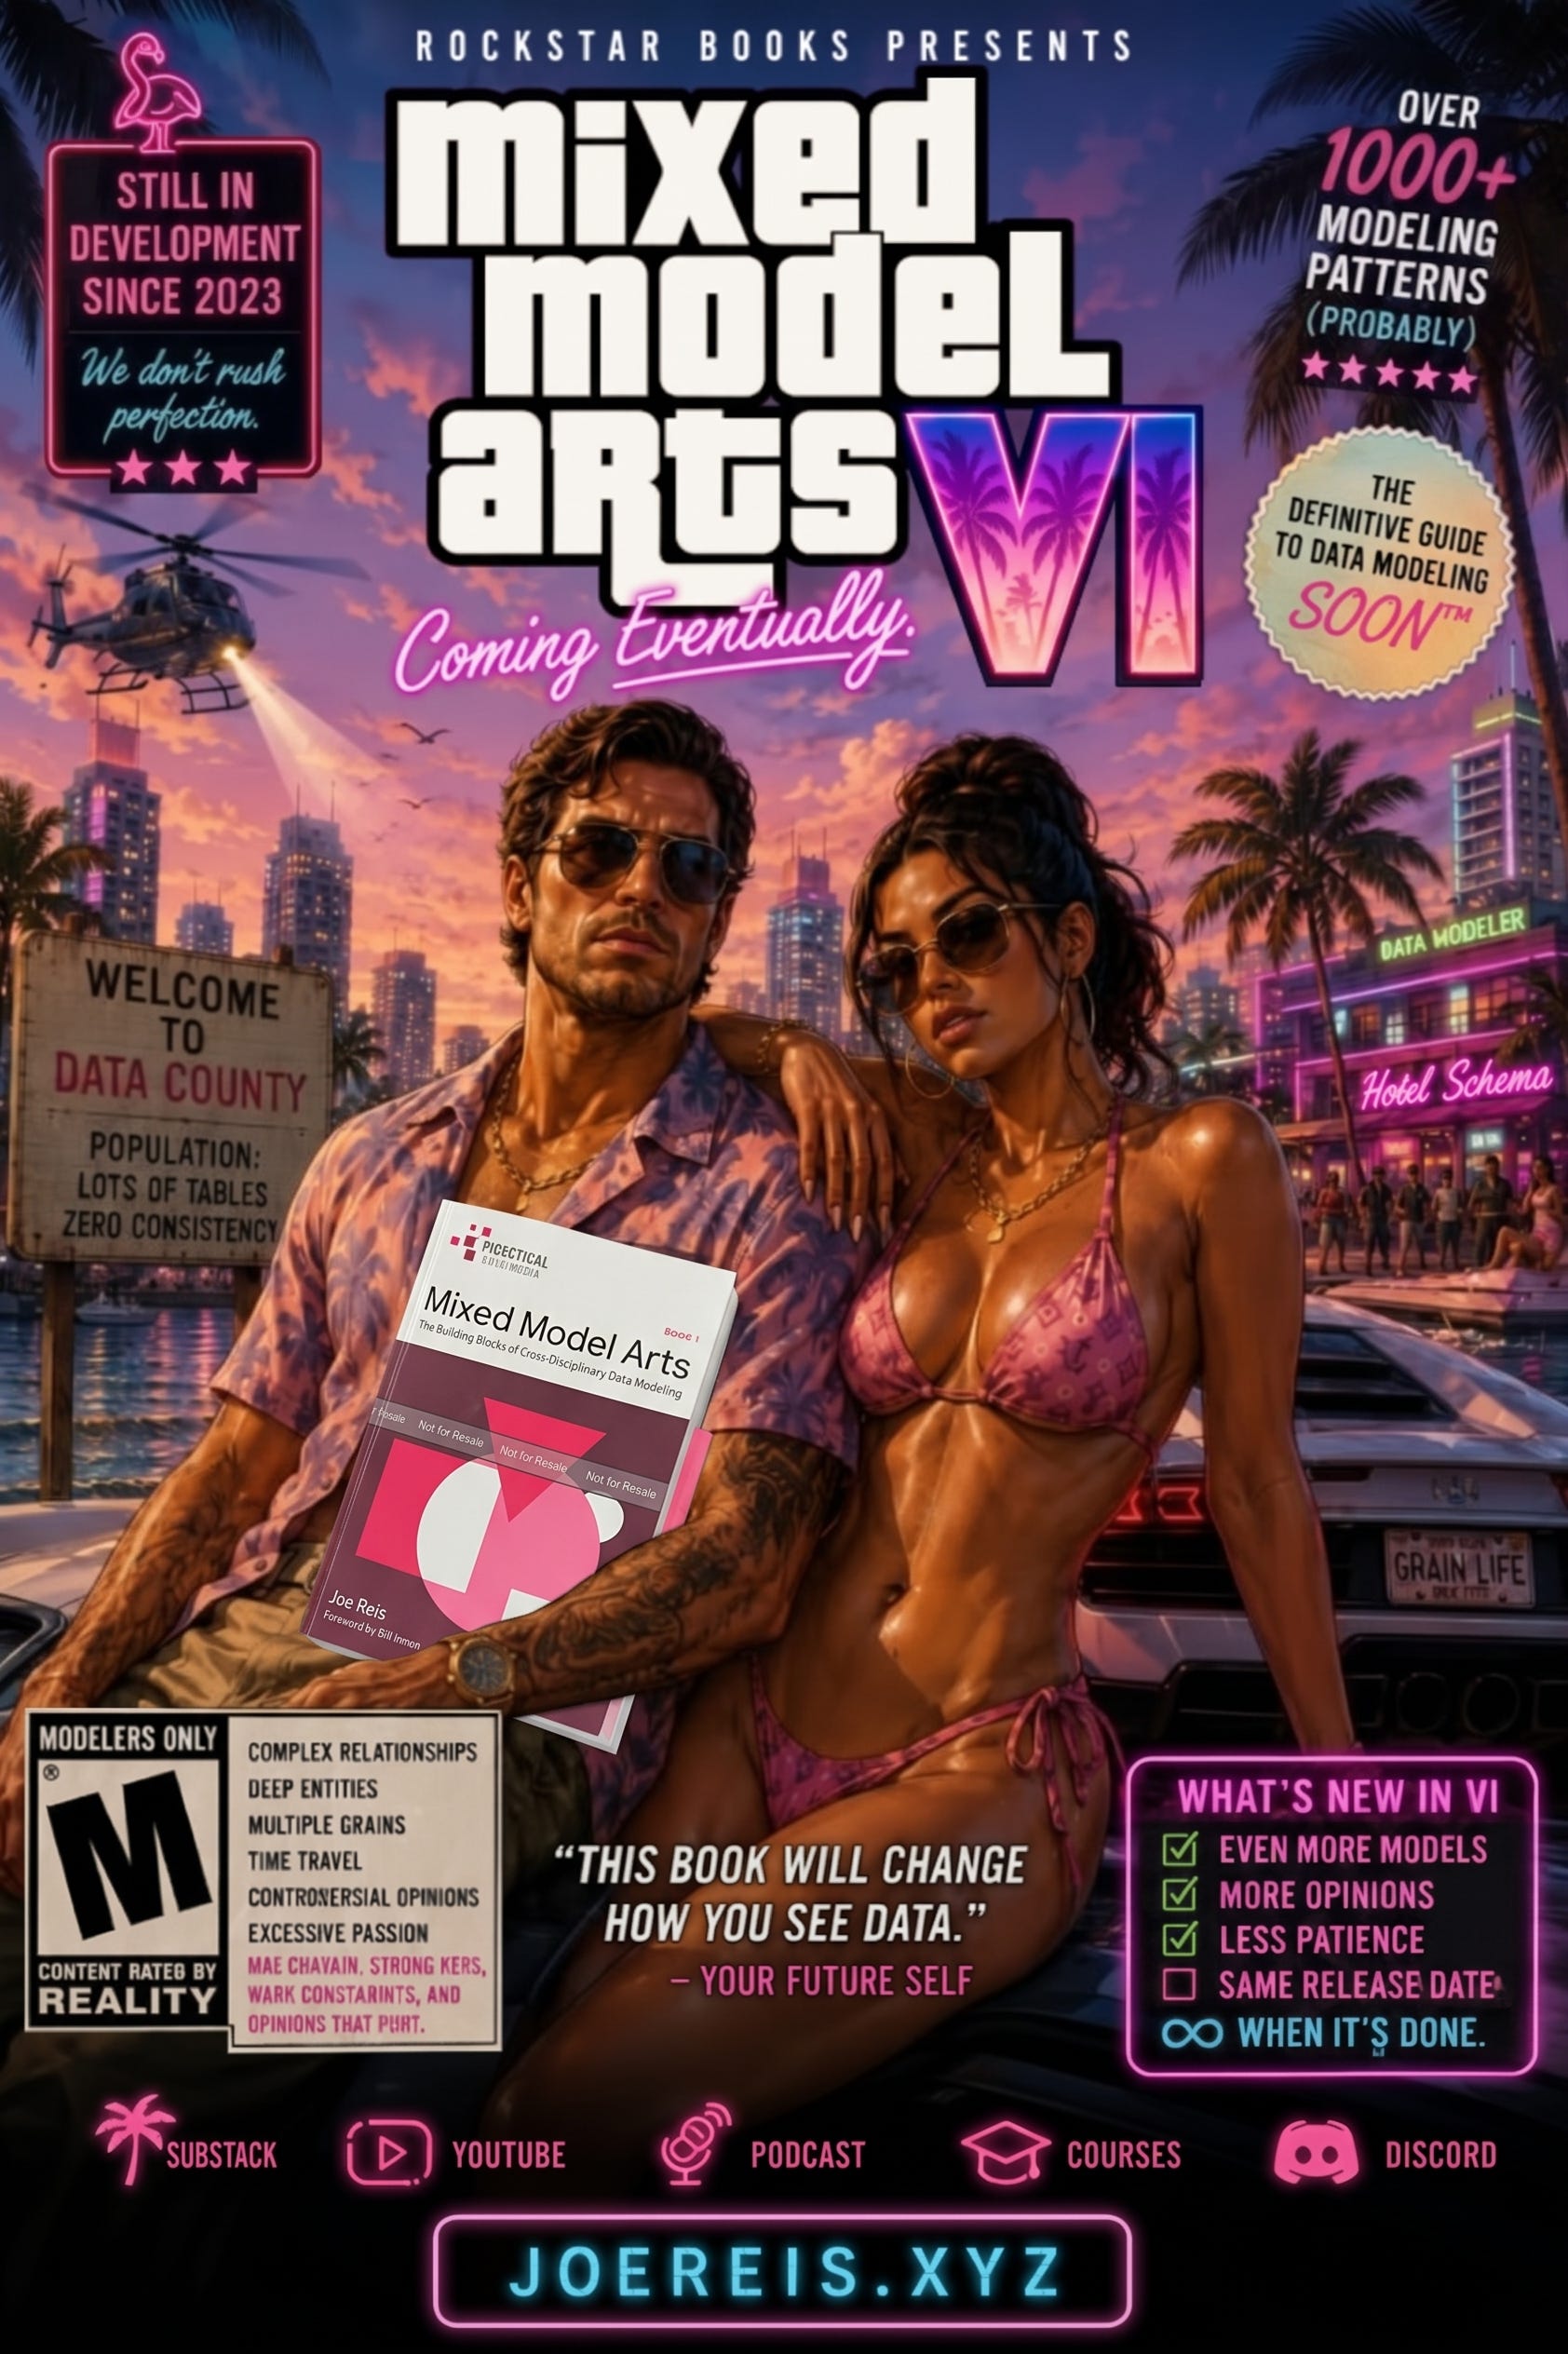
Mixed Model Arts is out, and I’m excited I beat GTA 6 to market. That’s all that matters, really. Also, based on the feedback on social media and Amazon rankings, the early success of the book is amazing. Please leave a review on Amazon!
Buy it on Amazon ($29.99 kindle, $49.99 paperback).
Buy the ebook direct ($29.99).
Or, subscribe to Practical Data Modeling, and get the ebook plus upcoming courses, community events, etc ($57 for now, price increasing very soon).
Where I’m At
Here’s an idea of what I’ll be doin. In most cases, I’m giving a talk. In some cases, I’m just hanging out.
- appliedAI. Munich. October 8.
- Hex Prompt. San Francisco. October 27.
- Stanford. November 2.
- Data Outpost. November 4-5. San Francisco. Register here. Get $100 off - Use PracData-100off at checkout.
- Connected Data London. November 11-12. Register here.
- Forward Data Conference. November 16. Paris. Register here.
- MLOps World. November 17-18. Austin. Register here.
More to be announced very soon.
Cool Videos and Reads
Why Data Modeling Matters MORE in the Age of AI. Mixed Model Arts w/ Ramona Truta
I usually run the show, but for this episode, we flipped the script. Ramona Truta took over the host chair and put me on the hot seat to talk about my book, Mixed Model Arts.
Here are some things I read this week that you might enjoy
No articles this week cuz didn’t read anything cuz traveling through Italy 🇮🇹
Note: These are articles I’ve read and enjoyed. I use AI to summarize my thoughts on the articles. I edit the summaries.
Find My Other Content Here
📺 YouTube - Interviews, tutorials, product reviews, rants, and more.
🎙️ Podcasts - Listen on Spotify or wherever you get your podcasts
📝 Practical Data Modeling - This is where I’m writing my upcoming book, Mixed Model Arts, mostly in public. Free and paid content.
If you’re interested in sponsoring my newsletter and podcast, Q3 and Q4 2026 are opening up. Space is very limited. Please fill out this form if you’re interested.
The Practical Data Community
The Practical Data Community is a place for candid, vendor-free conversations about all things tech, data, and AI. We host regular events such as book clubs, lunch-and-learns, Data Therapy, and more.
Thanks for reading! Subscribe for free to receive new posts and support my work.