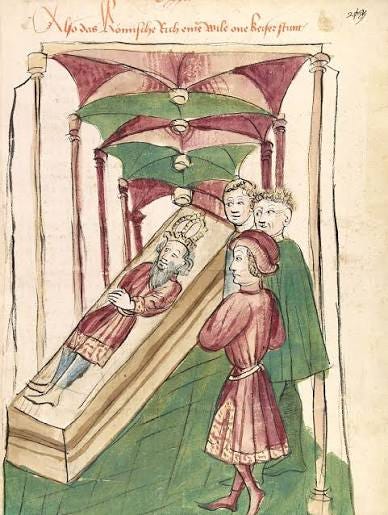
Depiction of the Interregnum in Chronicon pontificum et imperatorum (c. 1450), showing three men standing at the tomb of an emperor with the caption "Thus the Roman Empire for a time had no emperor" (Wikipedia)
Last month in Vegas, I was talking with Tristan Handy (co-founder of dbt, now President of Fivetran/dbt) about the state of the data industry. He used the word “interregnum”, which I think perfectly describes what I’ve been seeing recently.
The term reminded me of something Italian philosopher Antonio Gramsci wrote in his Prison Notebooks around 1930, when a lot in the world, like today, was in transition: “The crisis consists precisely in the fact that the old is dying and the new cannot be born; in this interregnum a great variety of morbid symptoms appear.”
Across the industry, symptoms of this shift are everywhere. We’re in what I think is the tail end of the consolidation phase. Fivetran and dbt merged. IBM bought Confluent. SAP bought Dremio. Salesforce bought Informatica. Snowflake and Databricks acquired Postgres platforms, among others. Meanwhile, almost every data vendor now claims their product was built for automated agents all along (I’m not so sure, but whatever).
But the old world still exists. The people working with data still have the same problems. Pipelines still break. Numbers still don’t reconcile. The business still can’t agree on what constitutes a customer.
The interregnum is that we’re being sold a new world while we’re still operating in the old one. The vendors are selling the future. The practitioners are maintaining the present. And the business is still waiting for Godot.
Welcome to the Great Data Interregnum.
The Modern Data Stack Was a “Phase,” Not a Law of Nature
I don’t think the Modern Data Stack died as an architecture. Its capabilities aren’t disappearing. Companies still need ingestion, transformation, orchestration, storage, governance, and analytics. What’s coming apart is the commercial arrangement around those capabilities.
The Modern Data Stack was built around a relatively simple proposition: assemble a data platform from independent, specialized components. Pick your warehouse, ingestion tool, transformation framework, orchestrator, catalog, observability vendor, and whatever else you needed. Swipe a credit card, stitch everything together, and off you go. At least that was the theory. Integration was often harder than the marketing suggested.
The Modern Data Stack’s heyday coincided with an extraordinary economic environment. Dirt-cheap capital (before and after COVID, thanks to the money carpet-bombed into the economy after the Great Financial Crisis), cloud infrastructure, and a seemingly endless appetite for SaaS made it possible to build venture-backed companies around increasingly narrow slices of functionality. There was genuine innovation. There was also enormous duplication, complexity, and what amounted to standalone companies built around features. Back then, you had to ask whether these companies had longevity or were just features, etc. Everyone wants to sell a shovel in a Gold Rush, and sometimes all you end up with is a plastic Spork.
Now the pendulum is violently swinging back. Fivetran and dbt combined ingestion and transformation. IBM acquired Confluent to strengthen its enterprise data and integration portfolio. SAP acquired Dremio. Salesforce absorbed Informatica. Snowflake and Databricks expanded into OLTP. NVIDIA, OpenAI, and Anthropic are also scooping up companies. I have friends at all of these companies, and I’m very happy for them. They’re very likely going to do very well.
The unbundling era is giving way to a rebundling era. But let’s not pretend AI explains everything. Some of this is market maturity. Some are slowing growth of the old guard (Modern Data Stack included). Some are the economics of consolidation. Some are competitive defenses. And yes, some are legitimately about new workloads created by AI. When every acquisition announcement invokes AI agents, it’s a sea of sameness.
The important distinction is that the capabilities of the Modern Data Stack aren’t disappearing. Rather, the companies and commercial boundaries around those capabilities are changing, often at a very uncomfortable pace.
And this is where things get interesting. Let’s look at some of the morbid symptoms.
Symptom 1: The Morbid Symptoms of Vendor Land
I spend a lot of time talking with data vendors. Lately, I’ve noticed four particularly strange symptoms.
Everyone Sounds EXACTLY THE SAME
Where vendors once belonged to distinct categories (observability, catalogs, ingestion, transformation, orchestration, etc.), almost everyone now sells an “AI foundation” or “context layer”, often both. When every tool claims the same role, differentiation disappears.
This creates a real problem for buyers. If every vendor uses identical language, identifying unique value or genuine differentiation becomes nearly impossible. For example, WTF is “context” when every vendor sells “context”? This isn’t a universally sellable thing available on a commodity exchange. Instead, it’s vendor-washing of an esoteric term nobody agrees on.
This creates a serious problem for buyers. If every vendor describes itself using the same terminology, how are customers supposed to understand what makes one product different from another? More importantly, how do vendors differentiate themselves?
In a market where a buyer can use AI to generate software that mimics a vendor’s product and create only the subset of features the buyer needs, standing out requires clear, distinct positioning.
The Buyer Is Changing, But…
Vendors increasingly target broader executive budgets rather than engineering budgets alone. The message often boils down to replacing or bypassing internal technical teams with automated systems. Every week, I see at least one new company pitching a “data team in a box.” Sidenote: most of these pitches and products are bullshit.
Automating wide swaths of the technical staff is the wet dream of executives who’ve spent years wondering why they need so many expensive engineers. There’s just one problem. The people who understand the systems, business processes, undocumented dependencies, and accumulated technical debt are often the same people the vendor is promising to eliminate. Imagine telling a data engineering team that your product will replace them, then asking that same team to implement it. Good luck with that.
We’ve seen versions of this before with self-service BI, no-code, and RPA. Each promised to democratize technical work and reduce dependence on specialists. And each succeeded to some degree without eliminating the underlying need for expertise.
AI is different because it genuinely automates meaningful portions of technical production. That’s not hype. But automating an activity isn’t the same as understanding the system it operates in.
You can sell around the data team. You can’t necessarily deploy around the data team. FAFO.
Agents as Producers and Consumers
Platforms are increasingly designed for agents as major data producers and consumers. These tools run continuously and consume significant infrastructure resources without interacting through standard user interfaces like UIs or CLIs.
This changes the economics and operational requirements of data platforms. Who manages access control for thousands of non-human identities? Who monitors their queries? Who evaluates their outputs? Who pays when they run inefficient workloads? And who’s responsible when an agent makes an incorrect decision using technically valid data?
Vendors are happy to sell the infrastructure for these workloads. The customer often bears responsibility for the consequences.
While agents work well in small, controlled environments, applying them across large organizations with complex policies and legacy systems introduces far greater technical challenges. Widespread adoption of agents in massive enterprises is still very low, and I think it will take longer than people think.
Independence Is Becoming a Moving Target
One of the Modern Data Stack's defining promises was choice. Buy independent products, connect them through open interfaces, and avoid depending too heavily on any single platform. But what happens when your independent vendor gets acquired by SAP, Salesforce, IBM, or another major platform?
Will the product remain equally useful outside the acquiring company’s ecosystem? Will the roadmap remain independent? What happens to pricing, licensing, and commercial leverage?
An acquisition doesn’t automatically destroy interoperability. But it changes the incentives. You only need to look at how once-loved products are now viewed with suspicion because their new overlords have different intentions. Customers should pay attention.
Symptom 2: The People Caught Between the Interregnum
Now let’s talk about the practitioners, because they’re the ones being asked to keep yesterday’s systems running while building tomorrow’s AI infrastructure.
The job market is sending contradictory signals. Some measures of traditional data and analytics hiring have weakened, while other studies show substantial growth in AI-oriented roles. Maybe traditional data engineering jobs are disappearing, while other numbers show they’re growing. Maybe roles are being renamed. The tech job market is grim, and I know plenty of people who have simply stopped looking for a job. Maybe we’re witnessing a more fundamental change in the composition of the work. Job titles alone won’t tell us.
I think the more important question is what happens when the work you’ve built your professional identity around becomes dramatically cheaper to produce. What if what you got paid a lot of money for is suddenly free for anyone to produce? For many types of technical tasks, we’re basically here.
Consider three categories of data work.
First, there’s the mechanical work: writing SQL, scaffolding dbt models, creating documentation, generating tests, configuring connectors, and producing the various artifacts that occupy much of an engineer’s day. AI is making a lot of this work extremely cheap and nearly instantaneous.
Second, there’s interpretation: understanding entities, grain, business definitions, semantics, system behavior, and the relationships between things. AI can assist here, too. But much of this work requires context that isn’t neatly documented anywhere.
Third, there’s accountability: determining whether something is correct, deciding which trade-offs matter, reconciling conflicting requirements, and taking responsibility when systems fail. This requires technical judgment and, frequently, organizational authority. You might have authority, or you might not.
None of these categories is immune to automation. But the relative economics are changing. The cost of producing technical artifacts is falling faster than the cost of deciding what to produce and whether it’s correct. Today, you can experiment with different scenarios and prototypes before deciding. What would’ve taken weeks or months is now a day’s work. Iteration is dirt cheap and done at warp speed.
That’s a consequential shift. It also creates an uncomfortable identity crisis.
I know plenty of engineers who love writing code, building pipelines, and optimizing infrastructure. I enjoy those things myself. But what happens when the part of your job you enjoy most is no longer the part the business values most?
The answer isn’t necessarily to become a product manager, business analyst, or “professional meeting attendee”. You need to become a more complete engineer, which is someone who understands systems, data, meaning, failure modes, and business objectives. In the past, that person was rare. Now, it’s becoming table stakes. Be someone who can move between implementation and abstraction, between technical details and organizational reality. Finally, be someone who knows not only how to build something, but why it should exist and how to tell whether it works, especially as the sheer volume of generated code and documentation begins to dwarf human capacity to read it.
Symptom 3: The Paradox of the Post-Literate Engineer
The sheer volume of code and documentation is a glaring wrinkle. As I discussed in my essay on the post-literate engineer, we’re entering a world where machines produce more code and documentation while humans may spend less time reading and writing those artifacts themselves. The volume of generated material is exploding like a supernova. Human attention simply doesn’t scale linearly. I know plenty of people who say, “I read everything the agent produces,” but who I also know have the attention span of a skateboard.
So what happens to review? If an agent can produce dozens of pull requests in the time it takes a human to inspect one, conventional review processes become a bottleneck. We’ll need more automated evaluation, stronger contracts, better testing, and new approaches to verifying generated systems.
But evaluation introduces its own problem. The pesky issue is that someone still has to decide what correctness means. Some laugh at me, call me a Boomer, and say that AI agents can sort this out. Perhaps, but let’s dig in a bit deeper.
Take a simple example. An agent is asked to calculate revenue. It can write the SQL, execute the query, produce a chart, and generate a convincing executive summary. But what counts as revenue? Gross or net? Recognized or invoiced? Which entities? Which time period? What about refunds?
Two executives (you probably work with them) might have two perfectly legitimate but incompatible definitions. The agent can automate the calculation. It cannot independently confer organizational authority on one definition over another. If you want to automate this with agents, go ahead. I’m sure plenty of people reading this article want your email for the cleanup from the aftermath.
This is why I’ve spent so much time writing about data modeling, semantics, and understanding the business in Mixed Model Arts. Not because everyone needs another modeling tool or ontology, but because understanding and representing the business becomes more important when machines can produce implementations at extraordinary speed. This is all we have right now, at least until the Singularity or whatever comes in post-human societies. But that’s a rant that could take up a book or two.
AI doesn’t magically eliminate ambiguity. It can industrialize ambiguity at machine speed, which is dangerous.
Symptom 4: The Double Burden
Practitioners face a particularly awkward transition. They still have to maintain Airflow DAGs, dbt projects, warehouse costs, access controls, and all the other infrastructure that keeps organizations running. Now they’re also expected to make everything “agent-ready.”
What does agent-ready mean? Ask five vendors, and you’ll probably get ten different answers, each conveniently aligned with whatever that vendor happens to sell.
Meanwhile, teams are dealing with more generated code, non-human identities, evaluation frameworks, agent access policies, cost management, and the challenge of making undocumented business processes explicit.
The new work hasn’t replaced the old work. It’s been piled on top. Practitioners have two competing burdens. That’s the interregnum in practice.
Plot Twist: The Next Unbundling May Already Be Happening
Here’s what makes this period especially interesting. We’re watching enormous consolidation across the vendor landscape. But in another conversation with Tristan this week, we discussed something that seems almost contradictory.
AI may already be enabling the next great unbundling.
Think about it. The original Modern Data Stack unbundled capabilities into specialized SaaS products. Now those companies are consolidating. But AI coding tools are making it increasingly practical for organizations to build their own specialized applications.
At a conference last week, I spoke with a team at a large company that’s replacing Tableau with internally developed React applications. A few minutes later, I encountered another team doing essentially the same thing. I also heard that a big frontier lab ripped out Big Data Platform, Inc. and moved their data to Iceberg. Zoom out, and these conversations are common. Teams are ripping out parts of the Modern Data Stack and replacing them with customized point solutions.
That’s anecdotal, not evidence of a wholesale industry migration. But the pattern is worth watching. What happens when companies no longer need to buy a specialized SaaS product for every narrow workflow? What happens when an organization can generate a purpose-built application on top of its existing data rather than purchasing another platform?
The economics of build versus buy are changing. Of course, generating an application isn’t the same as maintaining a reliable enterprise-grade product. Security, governance, accessibility, testing, and long-term ownership still matter. But the threshold for when building becomes economically attractive is dropping.
This creates a fascinating possibility. The industry could be consolidating at the platform and infrastructure layer while simultaneously unbundling at the application layer.
The next wave of specialized software might not appear on the MAD Machine Learning, AI & Data Landscape. It might be invisible to the outside, and instead generated inside enterprises, used by a handful of people, and never sold as a commercial product.
If that happens at scale, even the large consolidated platforms will face new competitive pressures. The pendulum may be swinging in both directions at once (quantum pendulums and stuff).
How Do You Operate in the Great Data Interregnum?
My simple advice: favor optionality over predictions.
Nobody has a particularly reliable track record of predicting where technology is going. And the pace of change makes long-term forecasts especially fragile. But you can control how much flexibility you preserve.
In Fundamentals of Data Engineering, Matt Housley and I discussed one-way and two-way doors. A two-way door is a decision you can reverse without catastrophic consequences. A one-way door is difficult or prohibitively expensive to reverse.
Right now, I’d be very cautious about walking through one-way architectural doors based on vendor marketing. That doesn’t mean avoiding proprietary platforms or insisting everything be open source. Portability has a cost. Sometimes the productivity advantages of an integrated platform outweigh the value of remaining independent. The key is understanding the trade-off before committing.
For practitioners, invest in skills that outlast the current tool cycle. Modeling, systems thinking, semantics, evaluation, software engineering, and understanding how businesses actually operate.
For data leaders, budget for flexibility in tooling and technology. Make ownership and authority explicit. Test agent systems against real organizational ambiguity, not polished vendor demos.
And for vendors, stop treating practitioners as obstacles to your executive sales pitch. Those practitioners may be the people responsible for implementing your product, keeping it running, and deciding whether it deserves to survive the next renewal. Respect them. Also, please find something more interesting to say than “agentic AI-powered data team in a box.”
What Comes After the Interregnum?
Predicting the exact outcome is impossible, but key areas to watch include whether data interfaces and definitions will standardize across platforms, how organizations will govern automated workloads, and how data engineering roles will evolve over the coming years.
But I’ll be watching a few things over the next year. Will agent-to-data interfaces and semantic contracts converge across competing platforms? Will enterprises develop repeatable ways to evaluate and govern agent-driven workloads? Will spending concentrate further around the largest platforms, or will AI-generated applications and open infrastructure create a new wave of unbundling? And what will a data engineer actually do in 2028?
I suspect the distinctions between some of today’s data roles will matter less. Modeling, engineering, evaluation, and agent operations will increasingly overlap. I also suspect the battle over who owns enterprise semantics and context will remain unresolved well into 2028.
Things Move On, but Also Stay Largely the Same
The Modern Data Stack was one particular arrangement of technologies, vendors, and labor that emerged under a particular set of economic conditions. Those conditions are changing. Tools are becoming more integrated. Interfaces are becoming more automated. The economics of producing software are shifting. And the companies that once defined the industry are reorganizing themselves around an uncertain future.
But the fundamental problems haven’t disappeared. We still have to understand what the business wants. We still have to figure out what’s right. We still have to deal with uncertainty, conflicting requirements, and failing systems.
That’s why I keep coming back to fundamentals. Not because the old ways of doing things should be preserved indefinitely, but because the underlying problems are more durable than the tools we invent to solve them.
The most important thing about this interregnum may be that it’s forcing us to distinguish the work that matters from the technologies we’ve used to perform it.
For vendors, the challenge is to find a genuinely differentiated place in whatever market emerges. For practitioners, it’s to become more complete, adaptable, and able to operate at multiple levels of abstraction. For leaders, it’s resisting the temptation to confuse automation with understanding.
And for everyone, it’s worth remembering that history doesn’t move neatly from one established order to another. Sometimes consolidation and unbundling happen simultaneously. Sometimes the next generation of technology makes the previous generation’s economics untenable before anyone has figured out a replacement. Sometimes you don’t recognize the new era until well after you’re already living in it.
That’s where I think we are.
The old data industry is fading away, and the new one hasn’t been born. And the morbid symptoms are just getting started.
In this Freestyle Friday episode, I chat about the various craziness and trends in data and AI right now.
Freestyle Fridays and my other podcasts are available on Spotify, Apple Podcasts, and wherever you get your podcasts. Please support the show with a review. It means a lot.
Mixed Model Arts
Mixed Model Arts is out. If you like the book, please leave a review on Amazon!
Buy it on Amazon ($29.99 Kindle, $49.99 paperback).
Buy the ebook directly ($29.99).
Or subscribe to Practical Data Modeling and get the ebook plus upcoming courses, community events, etc. ($57 for now; the price is increasing soon).
Where I’m At
Here’s what I’ll be doing. Most of the time, I’m giving a talk. Sometimes, I’m just hanging out.
- Data Outpost. November 4-5. San Francisco. Register here. Get $100 off - Use PracData-100off at checkout.
- Connected Data London. November 11-12. Register here.
- Lightdash Happy Hour. November 12. London. Register here.
- Forward Data Conference. November 16. Paris. Register here.
- MLOps World. November 17-18. Austin. Register here.
- Deeplearning.ai AI Dev NYC. November 30-December 1. Register here.
More to be announced very soon.
Find My Other Content Here
📺 YouTube - Interviews, tutorials, product reviews, rants, and more.
🎙️ Podcasts - Listen on Spotify or wherever you get your podcasts
📝 Practical Data Modeling - This is where I’m writing my upcoming book, Mixed Model Arts, mostly in public. Free and paid content.
The Practical Data Community
The Practical Data Community is a place for candid, vendor-free conversations about all things tech, data, and AI. We host regular events, including book clubs, lunch-and-learns, Data Therapy, and more.
Thanks for reading! Subscribe for free to receive new posts and support my work.